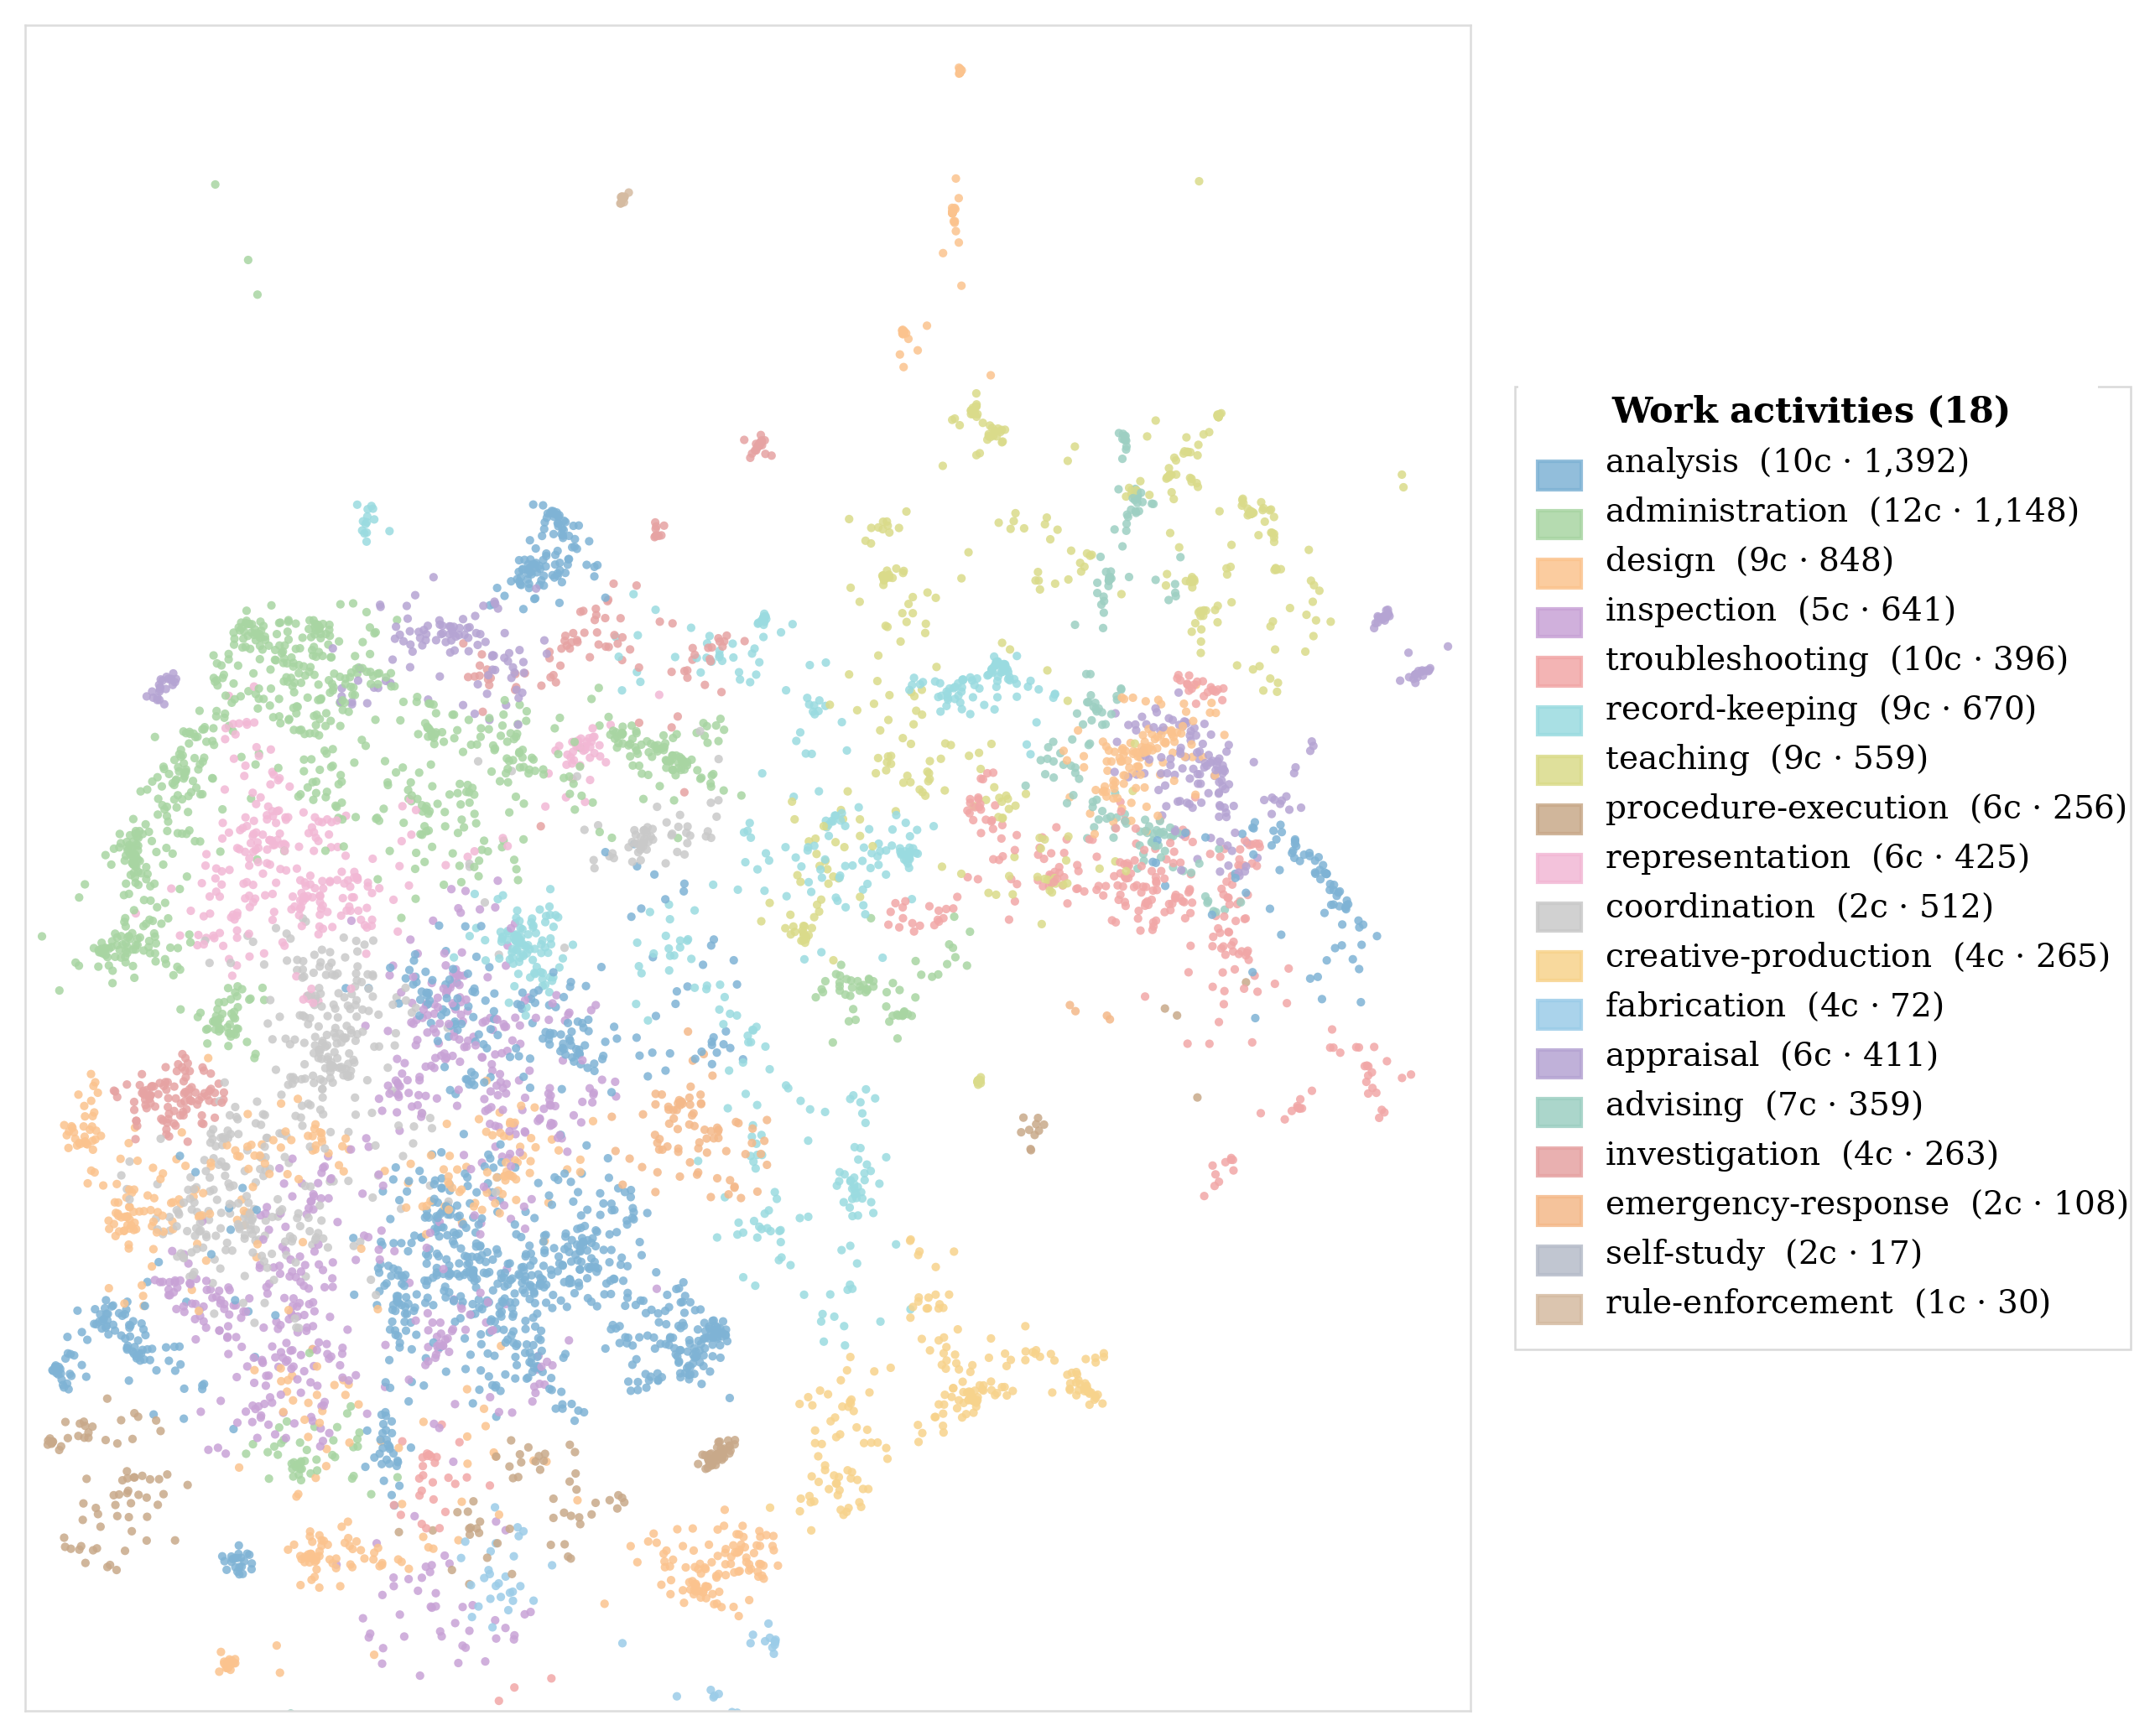
Figure 2 from the paper · Work-activity atlas of O*NET knowledge work
Method · Benchmark design
Designing Benchmarks for Knowledge Work
Specifies what knowledge-work agent benchmarks represent: the work activity, tested setting, required work product, and evaluated result. The accompanying reference derives an 18-activity inventory from O*NET task statements and applies the framework to existing agent benchmarks.
System view
Evaluation infrastructure · Open source
WorkWorlds: An Infrastructure for Evaluating AI Agents on Workplace Tasks
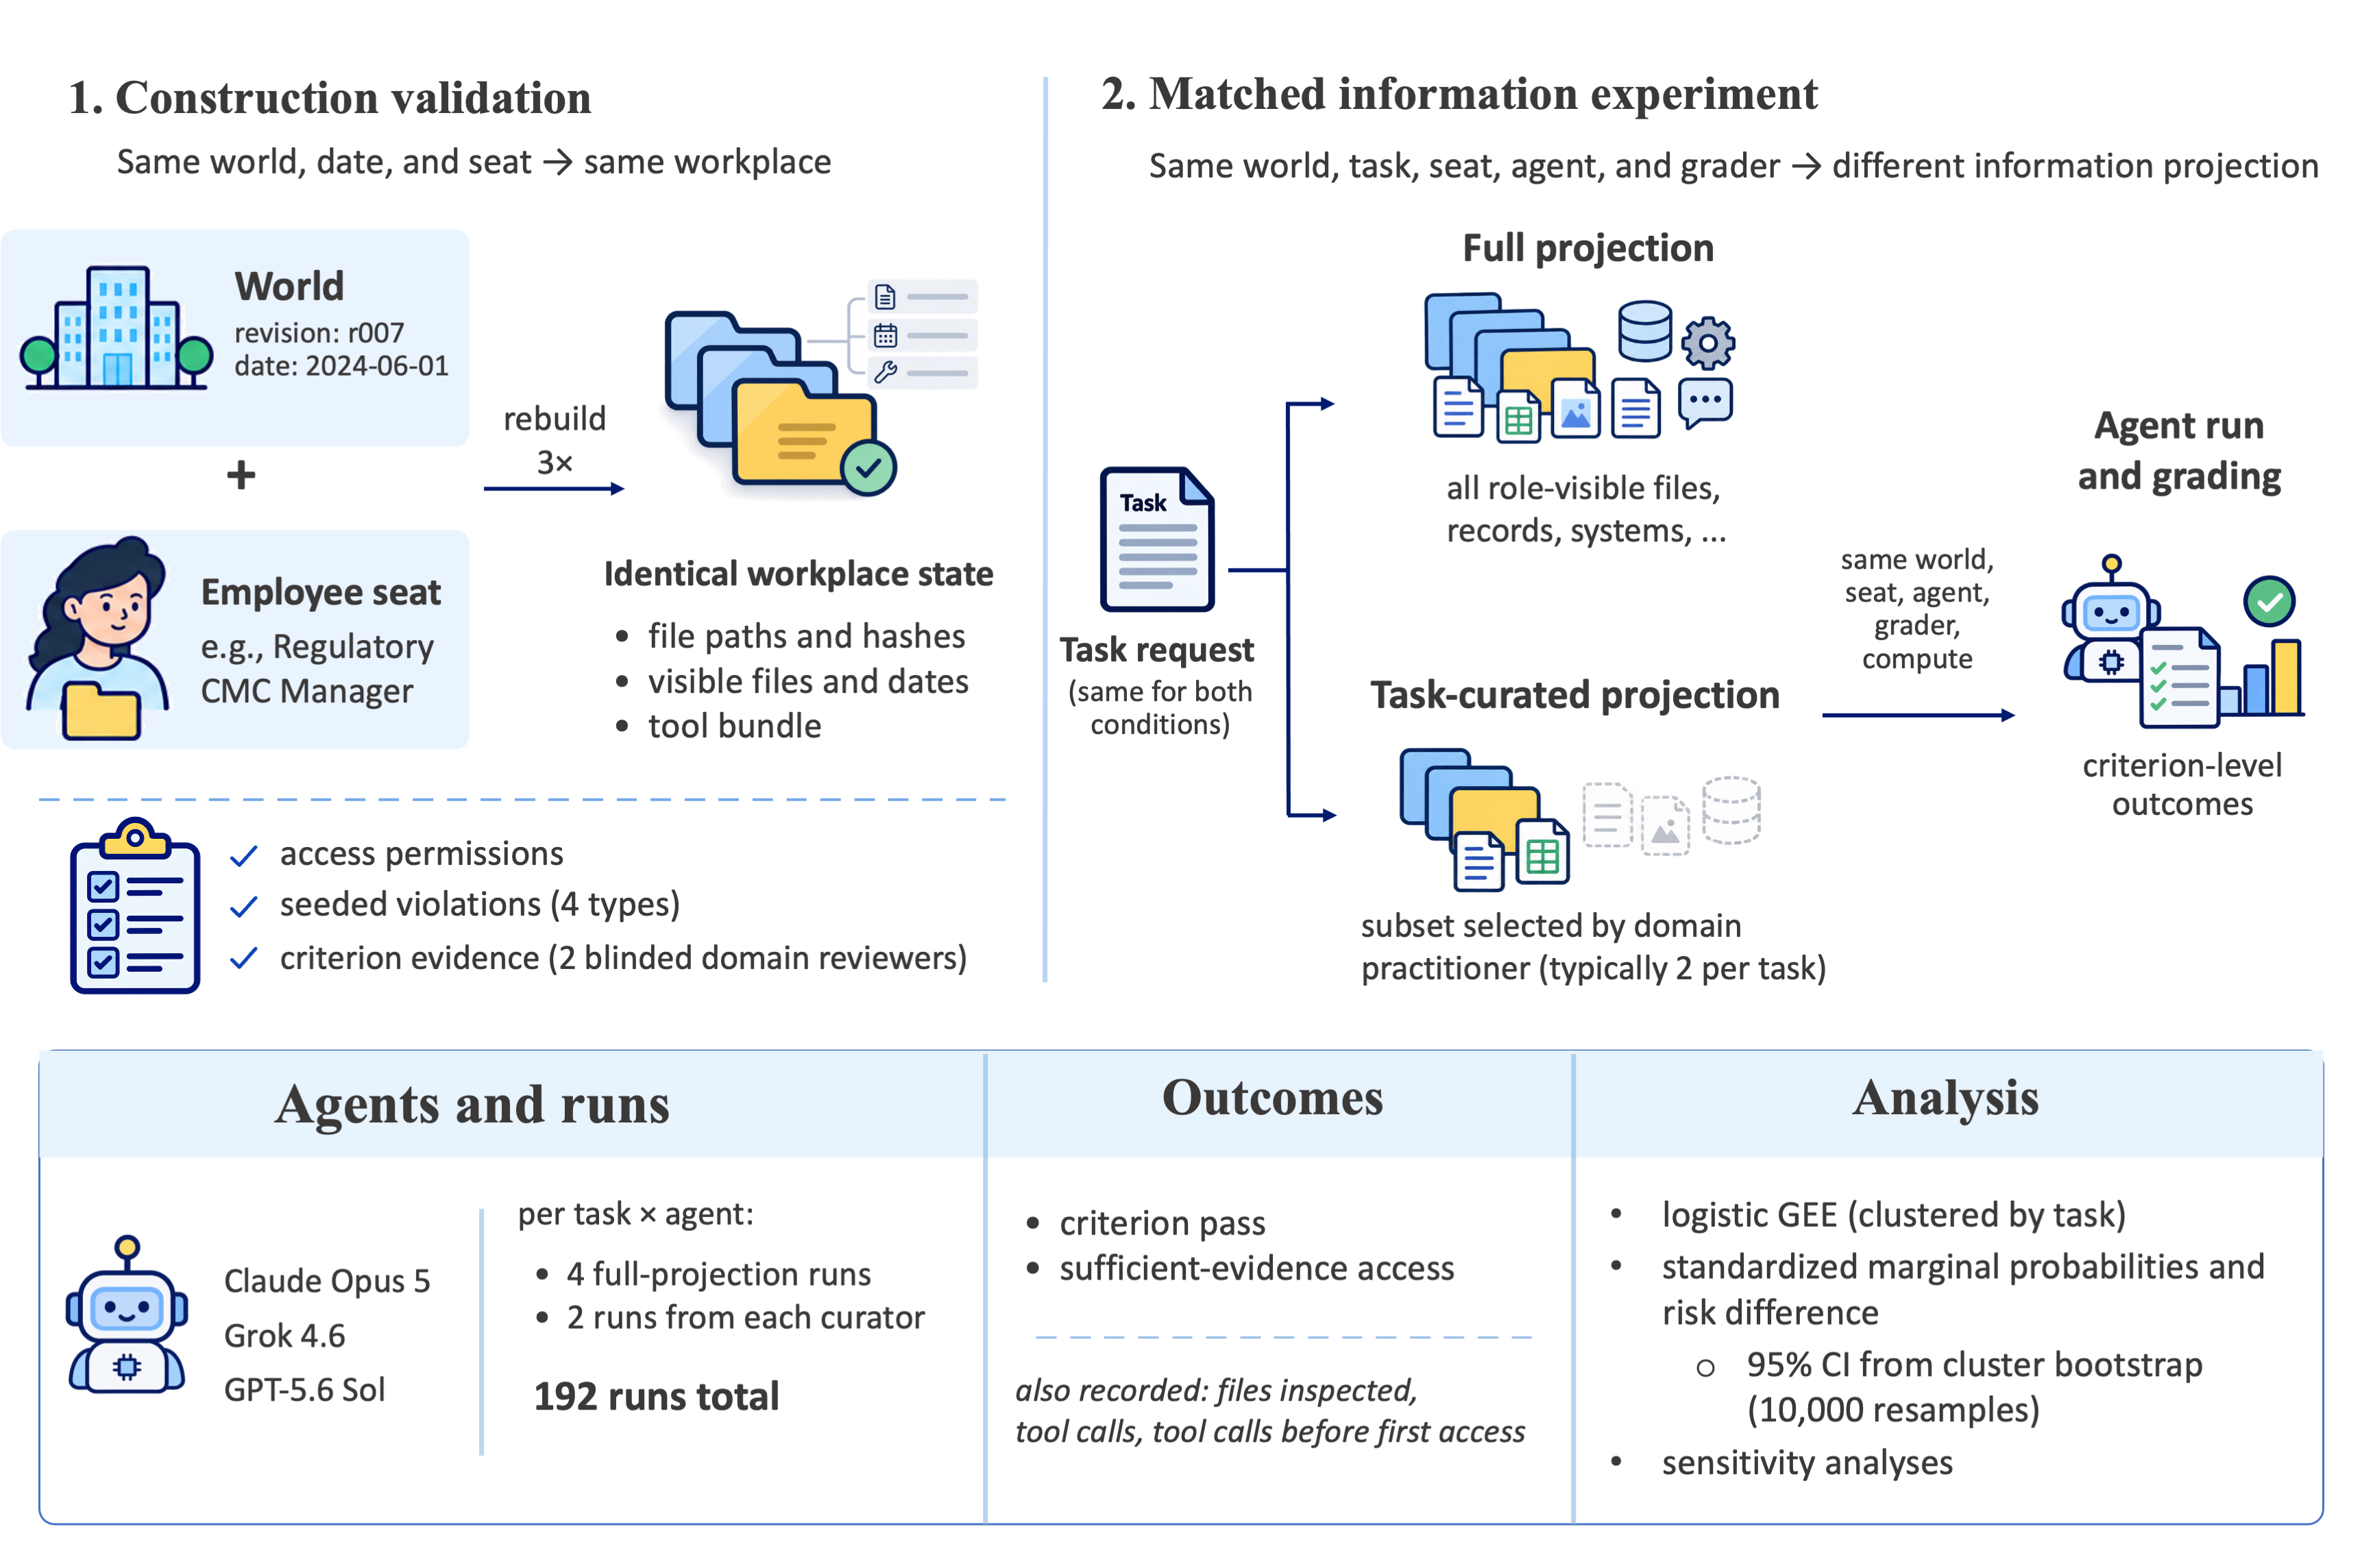
An evaluation system for reproducible workplace environments. WorkWorlds rebuilds an identical workplace state from a world revision and employee seat, then supports matched-information experiments comparing full and task-curated information projections under the same world, seat, agent, grader, and compute.
Important finding. Across 192 matched evaluations, moving from task-curated context to the full role-visible workplace reduced evidence access from 90.4% to 72.8% and criterion pass from 76.7% to 68.0%. Most of the difference occurred before the agent reached sufficient evidence.
Overview of harness-aware evaluation · Vector Institute
Community research · External resource
Harness-Aware Evaluation of LLM Agents
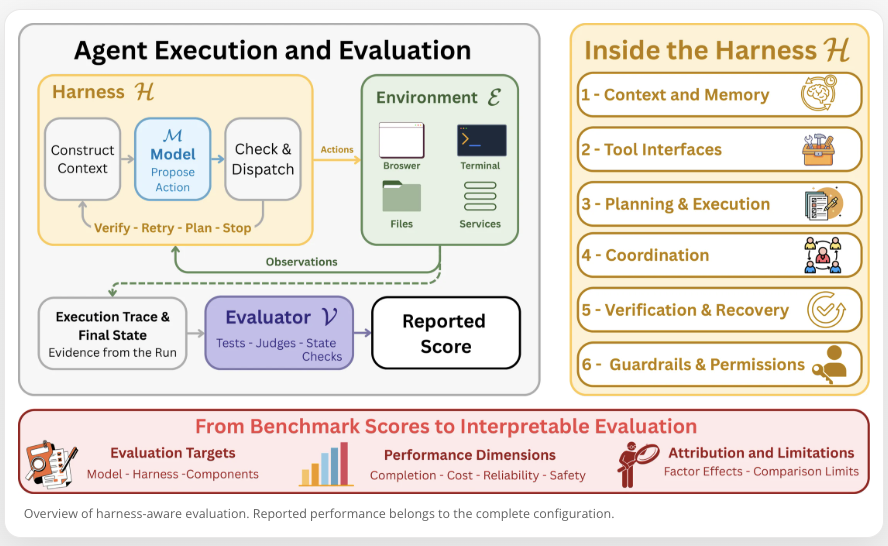
LLM-based agents combine model capabilities with memory, tools, and execution control. Changing this surrounding harness can alter performance and reverse model rankings, yet reports often omit configurations, resource budgets, or scoring procedures. Vector Institute's survey introduces a four-factor framework for harness-aware evaluation, maps representative systems and benchmarks, and provides reporting guidance for more consistent and reproducible comparisons.